
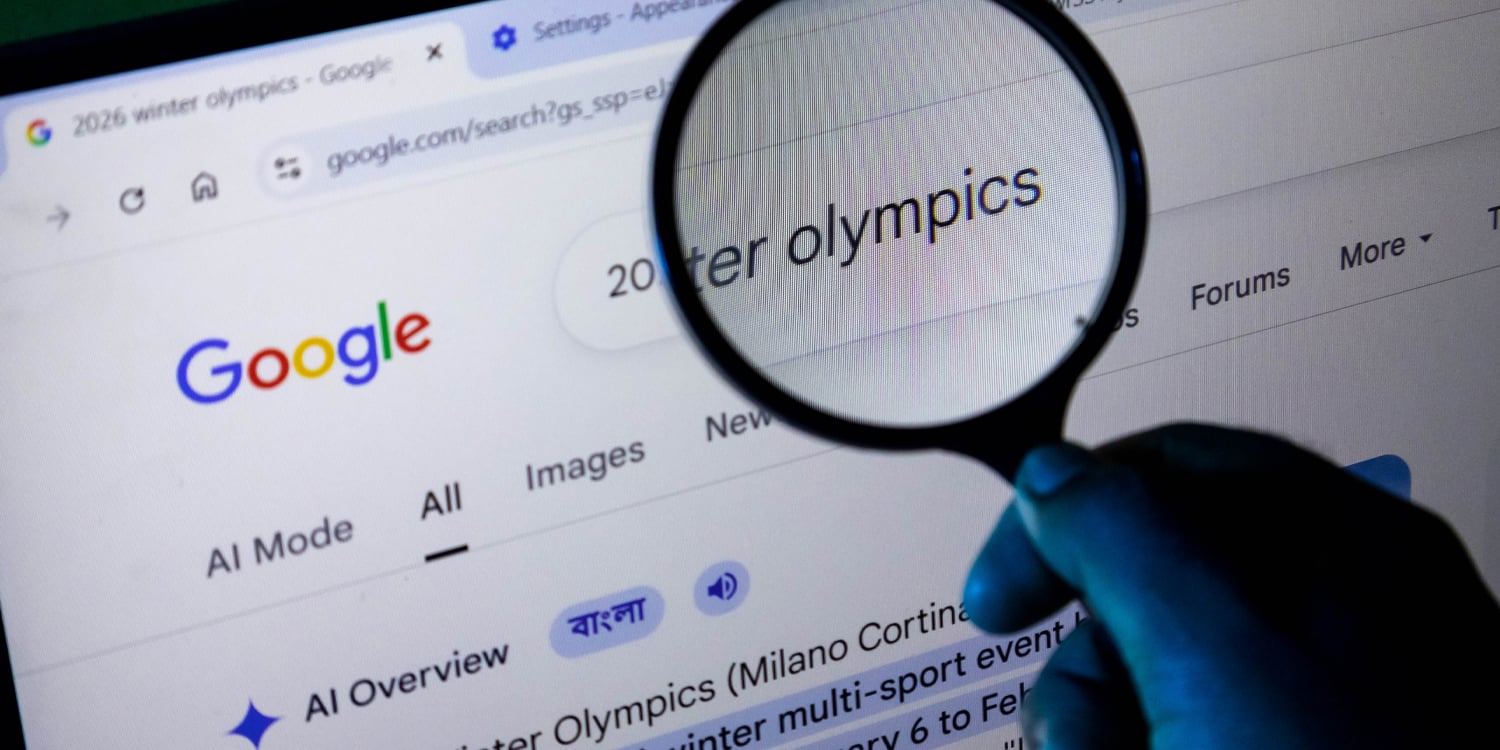
Google’s AI Overviews, a feature that reads multiple sources to craft a single, customised paragraph at the top of the search results, is increasingly shaping how users access information. A large-scale study finds these summaries activate in 13.7% of queries and can influence which sources readers see first, with potential consequences for publishers’ revenue. The research, led by Haofei Xu, Umar Iqbal and Jacob M. Montgomery of Washington University in St Louis, examined when the feature triggers, where it sources its material, how accurately it summarises those sources, and the economic impact on the original publishers.
The system relies on a sizeable language model that anchors its answers to retrieved web pages rather than relying solely on internal training data. This architecture aims to reduce hallucinations by binding the generated text to specific sources, while still producing a concise, user-facing paragraph at the top of the results page.
Over a 40-day period in early 2026, the researchers ran 55,393 trending Google queries using an automated web-browsing programme, spread across 19 topical categories such as health, sport and politics. The programme was designed to mimic natural typing and avoid bot detection, and the team logged whether an AI Overview appeared, the content of the summary, and the external websites cited.
The analysis found AI Overviews activated for 13.7% of queries. The likelihood of a generated summary depended heavily on the user’s prompt: a direct question yielded a generated overview in 64.7% of cases, compared with 9.5% for standard keyword searches.
The activation rate also varied by topic. The feature appeared more frequently for hobbies and science queries and less often for politically sensitive subjects, suggesting Google exercises undisclosed editorial discretion in deciding when to deploy the AI tool.
The researchers assessed the credibility of the sources cited by AI Overviews against the traditional first-page results using an established metric for domain quality. They found the AI-generated summaries tended to rely on more credible sources and avoided a large share of user-generated content such as social media posts or video platforms.
Nonetheless, about 30% of the websites cited in AI Overviews did not appear on the first page of the regular search results, indicating the system uses a distinct selection process that surfaces different sites for the same prompt.
To check factual accuracy, the team broke down 98,020 individual claims within the overviews. They built an automated verification pipeline using a separate large language model to read the cited pages and determine whether each generated claim was supported by the source material. They found that 11% of the generated claims were not supported by the cited pages; most errors were omissions, with a smaller number contradicting the text of the source itself.
Importantly, the researchers noted that using higher-quality sources did not eliminate the error rate, and there was no statistical relationship between a site’s credibility and the likelihood of an accurate summary. Accuracy also varied by topic: health and political summaries tended to be more reliable than those about entertainment or technology.
The study also examined the economic implications for publishers. It found that more than half of the pages cited by AI Overviews contained digital advertisements. When a user receives a synthesized answer directly on the search page, they are less likely to click through to the original site, reducing potential ad revenue for the publishers who produced the content.
There is an asymmetry in this arrangement: while publishers lose direct traffic to their sites, Google continues to display its own sponsored advertisements alongside the AI Overviews, and in some cases places ads above the generated summaries themselves.
The researchers acknowledged certain limitations. Live, updating queries could introduce errors in their verification methods if source pages changed after the summary was generated. The study also excluded sites that require authentication or block automated scraping, such as major social media platforms, meaning some potentially relevant data were not assessed.
Future research, they say, should measure how users interact with these search summaries in real-world settings and across diverse demographics, to determine whether citation errors alter beliefs on high-stakes topics.
The study is titled “Measuring Google AI Overviews: Activation, Source Quality, Claim Fidelity, and Publisher Impact” and was authored by Haofei Xu, Umar Iqbal, and Jacob M. Montgomery.
